数据库迁移中的数据一致性保障与校验机制
原创
数据库迁移中的数据一致性保障与校验机制
原创
用户12605543
发布于 2026-07-15 11:48:22
发布于 2026-07-15 11:48:22
一、数据一致性概述
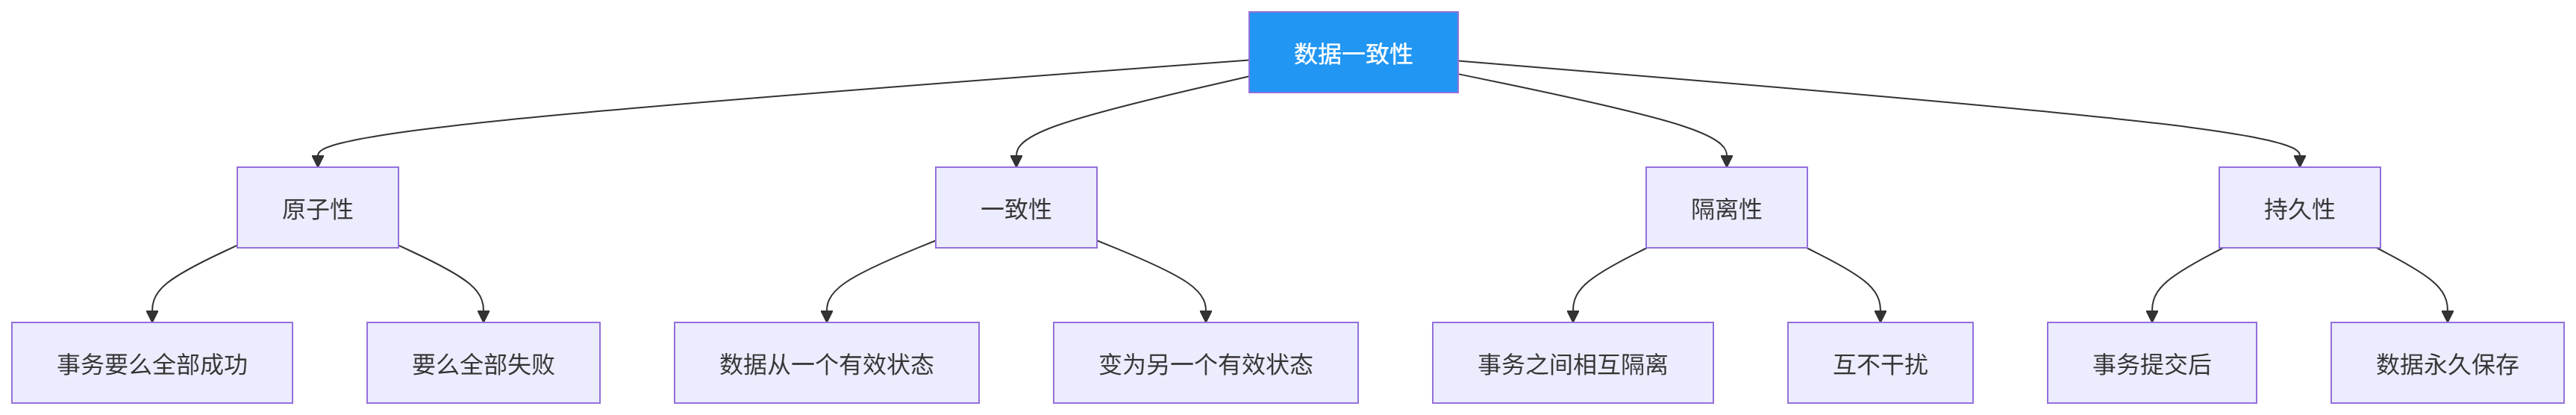
图表
二、迁移过程中的一致性风险
2.1 一致性风险类型
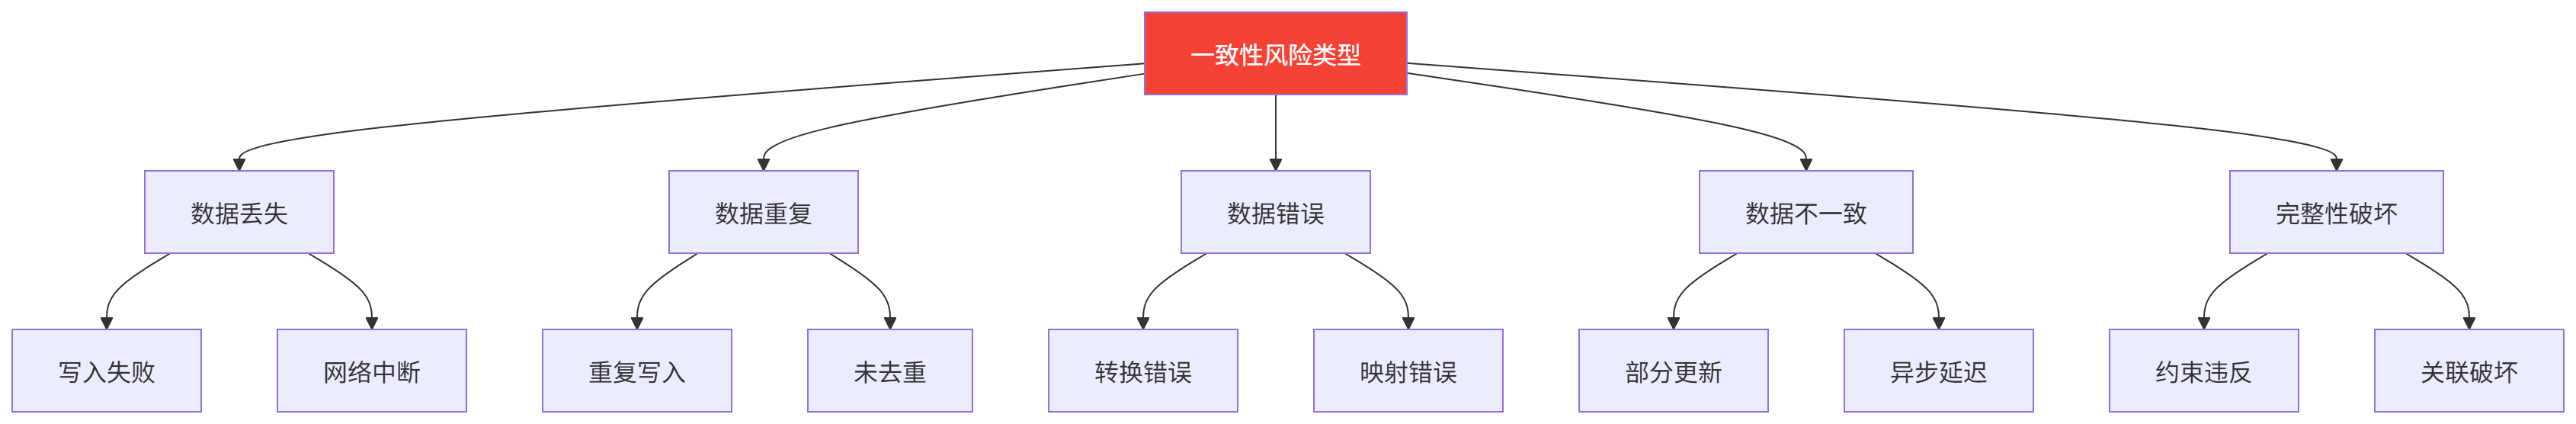
图表
2.2 风险影响评估
风险类型 | 影响程度 | 发生概率 | 优先级 |
|---|---|---|---|
数据丢失 | 高 | 中 | 高 |
数据重复 | 中 | 高 | 高 |
数据错误 | 中 | 中 | 中 |
数据不一致 | 中 | 中 | 中 |
完整性破坏 | 高 | 低 | 高 |
三、一致性保障策略
3.1 事务保障
事务迁移流程:
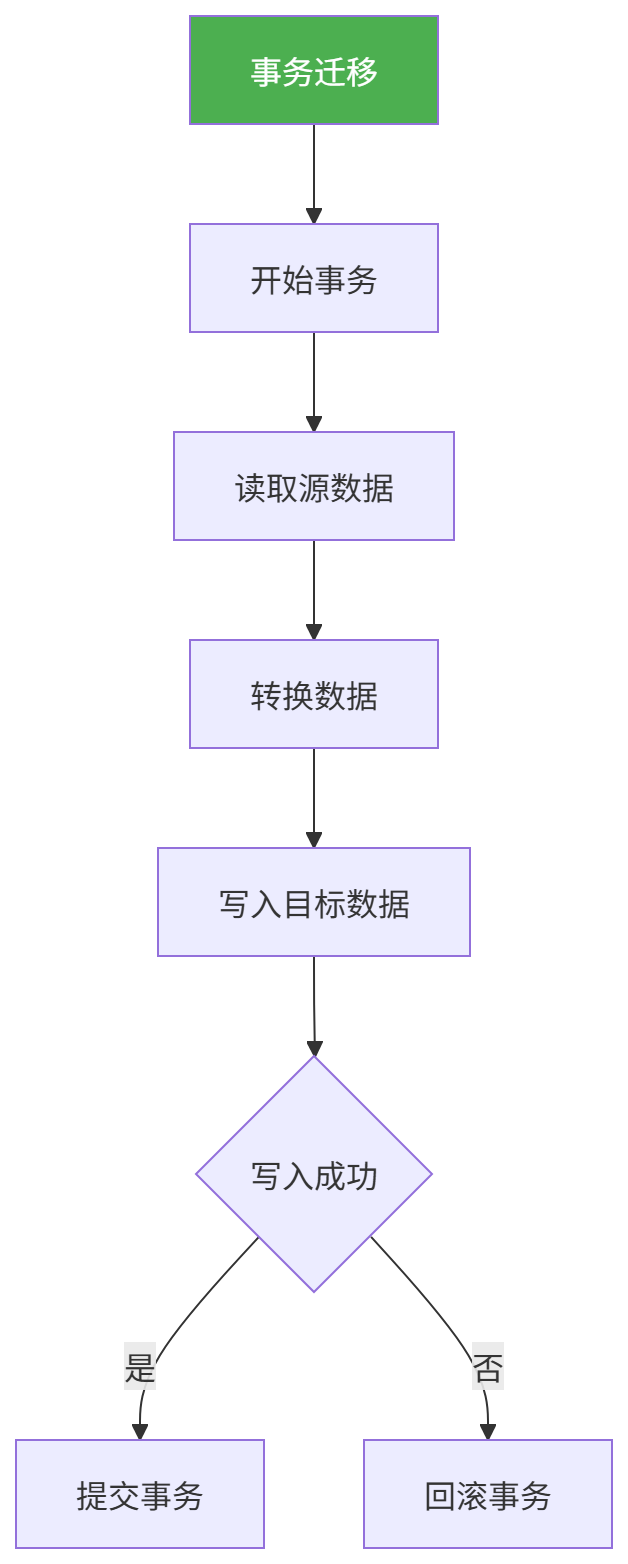
图表
事务隔离级别:
隔离级别 | 说明 | 适用场景 |
|---|---|---|
READ UNCOMMITTED | 读取未提交数据 | 不重要数据 |
READ COMMITTED | 读取已提交数据 | 一般业务 |
REPEATABLE READ | 可重复读 | 重要业务 |
SERIALIZABLE | 串行化 | 核心业务 |
3.2 幂等性保障
幂等性设计:
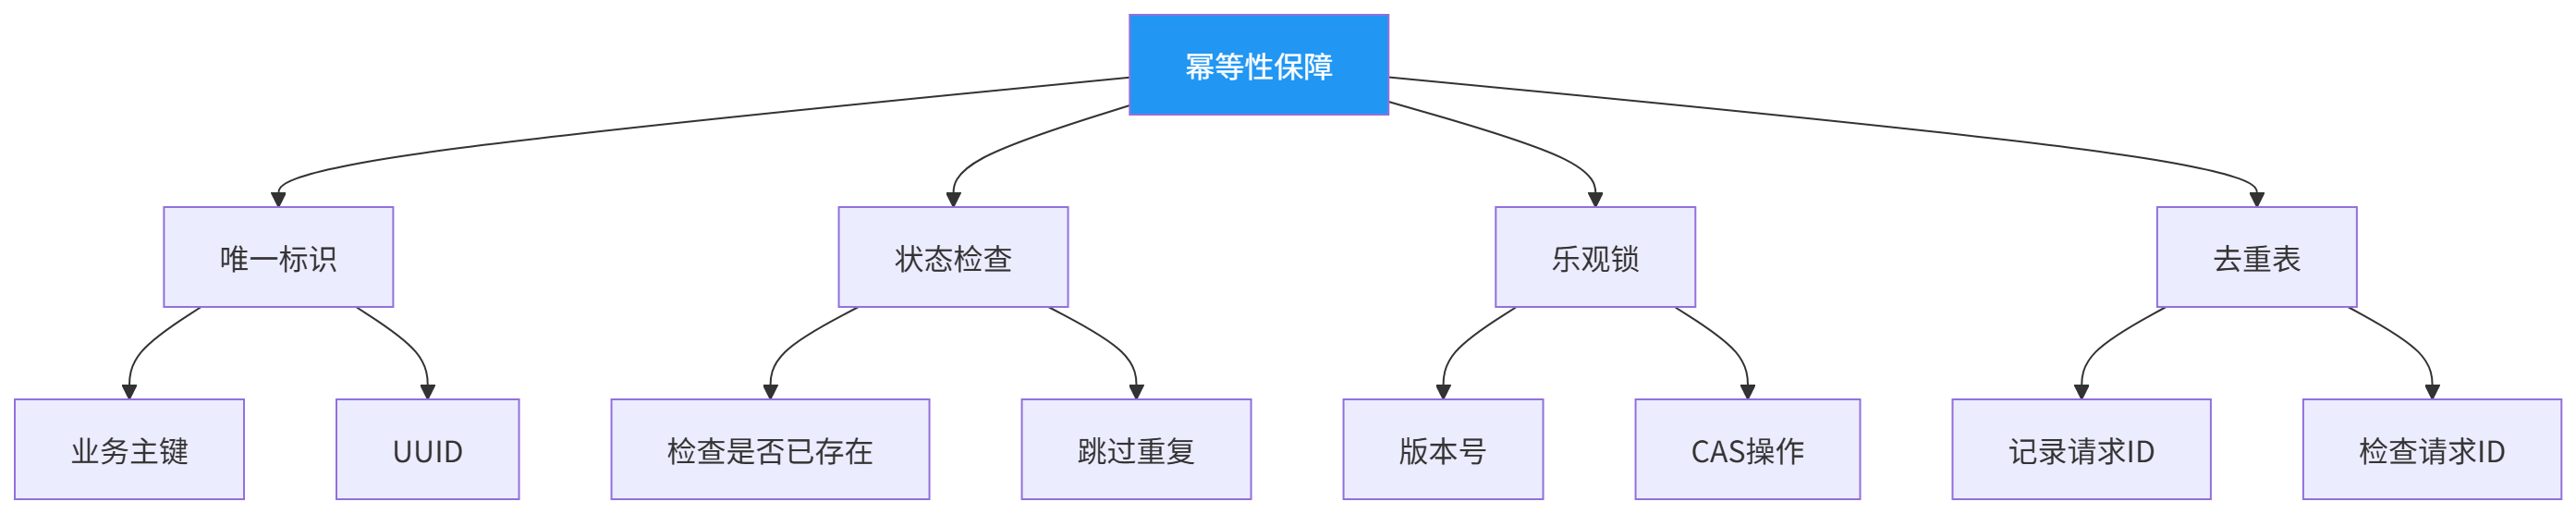
图表
幂等性代码示例:
import uuid

class IdempotentMigration:
    def __init__(self, db):
        self.db = db

    def generate_request_id(self):
        return str(uuid.uuid4())

    def check_request_id(self, request_id):
        result = self.db.execute(
            "SELECT COUNT(*) FROM migration_requests WHERE request_id = %s",
            (request_id,)
        )
        return result.fetchone()[0] > 0

    def save_request_id(self, request_id):
        self.db.execute(
            "INSERT INTO migration_requests (request_id, status, created_at) VALUES (%s, %s, NOW())",
            (request_id, 'processing')
        )

    def update_request_status(self, request_id, status):
        self.db.execute(
            "UPDATE migration_requests SET status = %s, updated_at = NOW() WHERE request_id = %s",
            (status, request_id)
        )

    def migrate_with_idempotency(self, data, request_id=None):
        if request_id is None:
            request_id = self.generate_request_id()

        if self.check_request_id(request_id):
            print(f"Request {request_id} already processed")
            return {'success': True, 'message': 'Already processed'}

        try:
            self.save_request_id(request_id)

            with self.db.begin():
                self._migrate_data(data)

            self.update_request_status(request_id, 'success')
            return {'success': True, 'message': 'Migration successful'}

        except Exception as e:
            self.update_request_status(request_id, 'failed')
            return {'success': False, 'message': str(e)}

    def _migrate_data(self, data):
        for record in data:
            existing = self.db.execute(
                "SELECT id FROM target_table WHERE id = %s",
                (record['id'],)
            ).fetchone()

            if existing:
                self.db.execute(
                    "UPDATE target_table SET name = %s, email = %s WHERE id = %s",
                    (record['name'], record['email'], record['id'])
                )
            else:
                self.db.execute(
                    "INSERT INTO target_table (id, name, email) VALUES (%s, %s, %s)",
                    (record['id'], record['name'], record['email'])
                )
3.3 分布式锁
分布式锁实现:
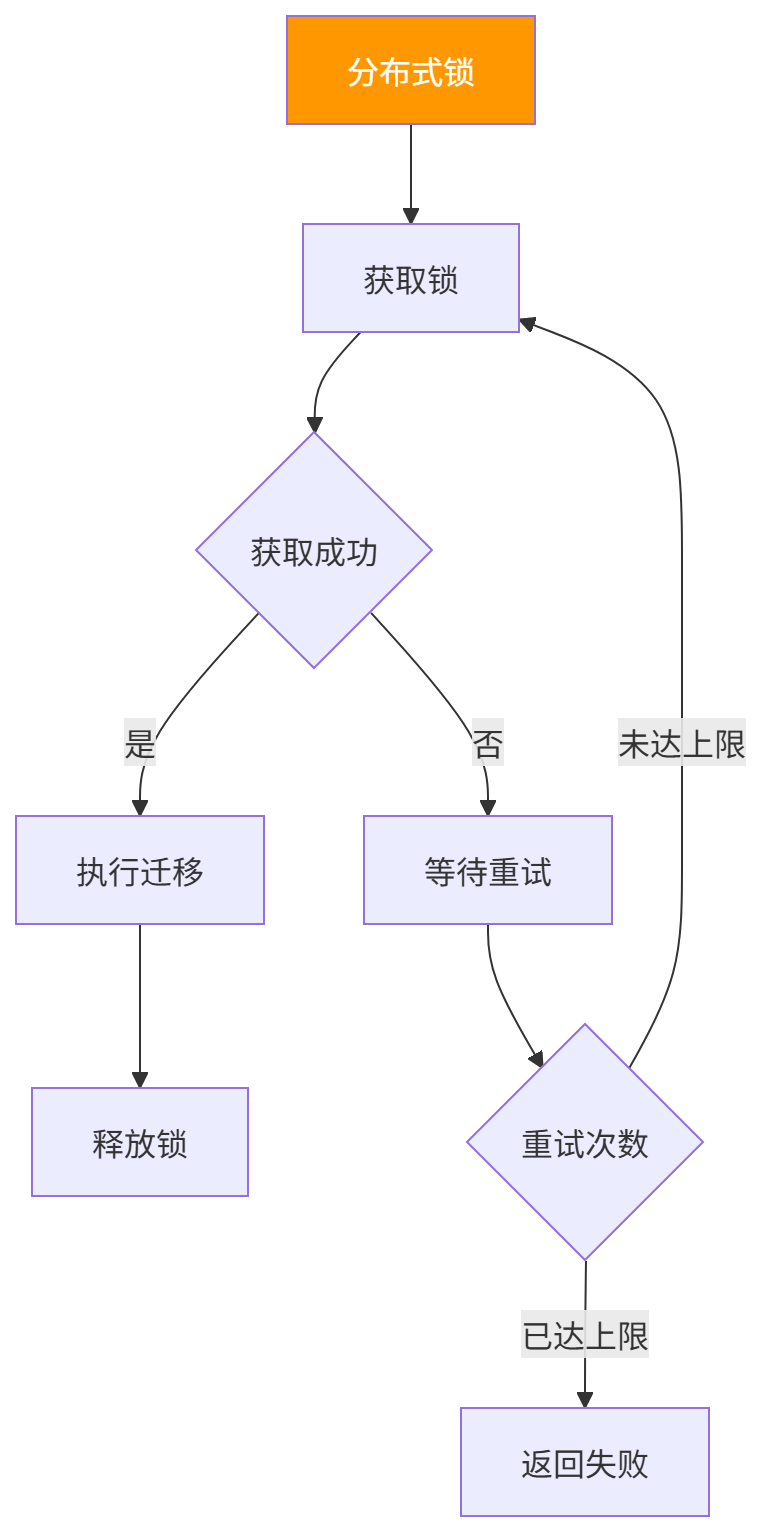
图表
Redis分布式锁代码示例:
import redis
import time

class DistributedLock:
    def __init__(self, redis_client, lock_key, expire_time=30):
        self.redis = redis_client
        self.lock_key = lock_key
        self.expire_time = expire_time
        self.lock_value = None

    def acquire(self, timeout=10):
        end_time = time.time() + timeout

        while time.time() < end_time:
            self.lock_value = str(uuid.uuid4())
            result = self.redis.set(
                self.lock_key,
                self.lock_value,
                nx=True,
                ex=self.expire_time
            )

            if result:
                return True

            time.sleep(0.1)

        return False

    def release(self):
        if self.lock_value:
            script = """
                if redis.call("get", KEYS[1]) == ARGV[1] then
                    return redis.call("del", KEYS[1])
                else
                    return 0
                end
            """
            self.redis.eval(script, 1, self.lock_key, self.lock_value)

    def __enter__(self):
        self.acquire()
        return self

    def __exit__(self, exc_type, exc_val, exc_tb):
        self.release()
3.4 数据校验点
校验点机制:
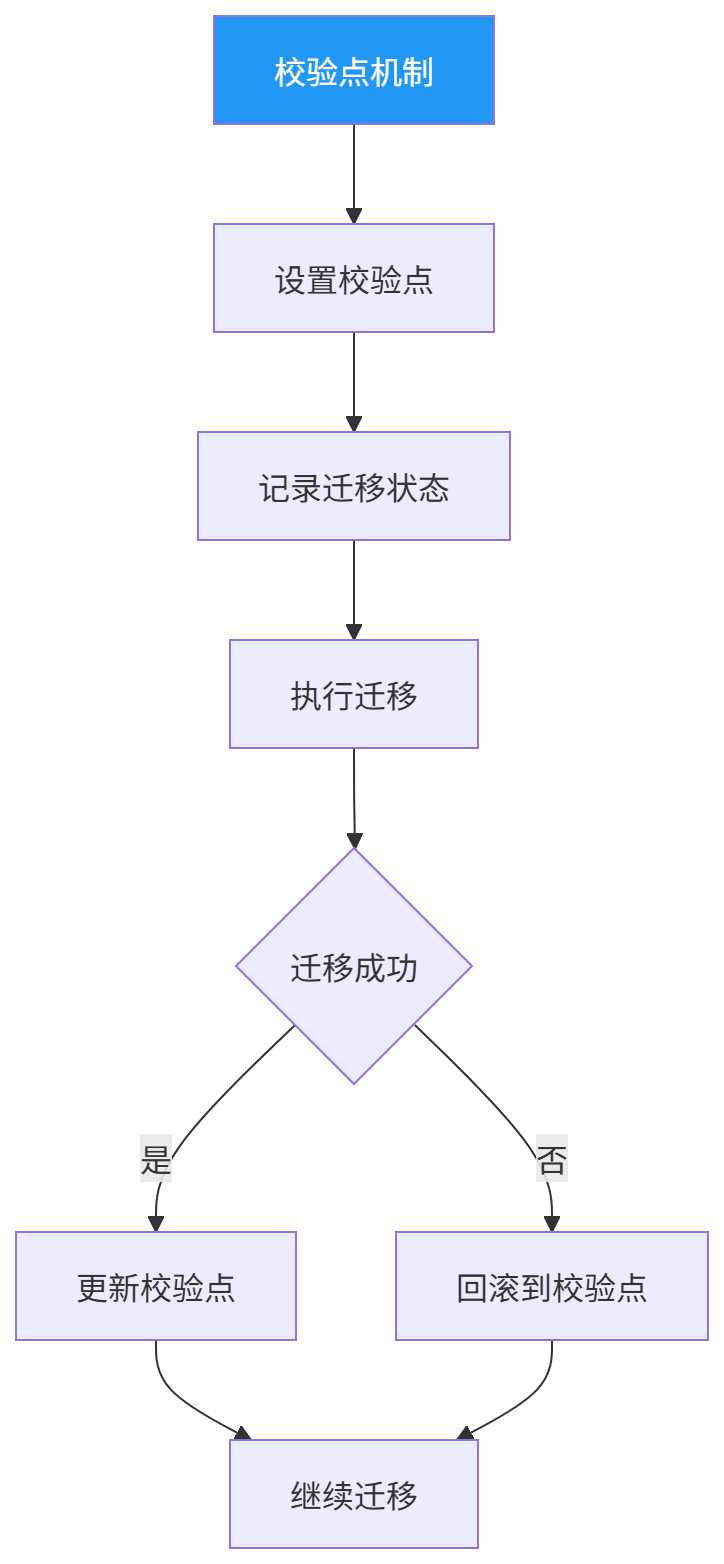
图表
校验点实现:
class CheckpointMigration:
    def __init__(self, db):
        self.db = db

    def get_checkpoint(self, migration_id):
        result = self.db.execute(
            "SELECT position, status FROM migration_checkpoints WHERE migration_id = %s",
            (migration_id,)
        ).fetchone()

        if result:
            return {'position': result[0], 'status': result[1]}
        return {'position': 0, 'status': 'pending'}

    def set_checkpoint(self, migration_id, position, status):
        existing = self.db.execute(
            "SELECT id FROM migration_checkpoints WHERE migration_id = %s",
            (migration_id,)
        ).fetchone()

        if existing:
            self.db.execute(
                "UPDATE migration_checkpoints SET position = %s, status = %s, updated_at = NOW() WHERE migration_id = %s",
                (position, status, migration_id)
            )
        else:
            self.db.execute(
                "INSERT INTO migration_checkpoints (migration_id, position, status, created_at) VALUES (%s, %s, %s, NOW())",
                (migration_id, position, status)
            )

    def run_migration(self, migration_id, data, batch_size=1000):
        checkpoint = self.get_checkpoint(migration_id)
        start_pos = checkpoint['position']
        total_records = len(data)

        print(f"Resuming migration from position {start_pos}")

        for i in range(start_pos, total_records, batch_size):
            batch = data[i:i+batch_size]

            try:
                with self.db.begin():
                    self._process_batch(batch)

                self.set_checkpoint(migration_id, i + len(batch), 'processing')
                print(f"Migrated {i + len(batch)}/{total_records} records")

            except Exception as e:
                print(f"Error at position {i}: {e}")
                self.set_checkpoint(migration_id, i, 'failed')
                raise

        self.set_checkpoint(migration_id, total_records, 'completed')
        print("Migration completed successfully")

    def _process_batch(self, batch):
        for record in batch:
            self.db.execute(
                "INSERT INTO target_table (id, name, email) VALUES (%s, %s, %s) ON DUPLICATE KEY UPDATE name = %s, email = %s",
                (record['id'], record['name'], record['email'], record['name'], record['email'])
            )
四、数据校验机制
4.1 校验类型
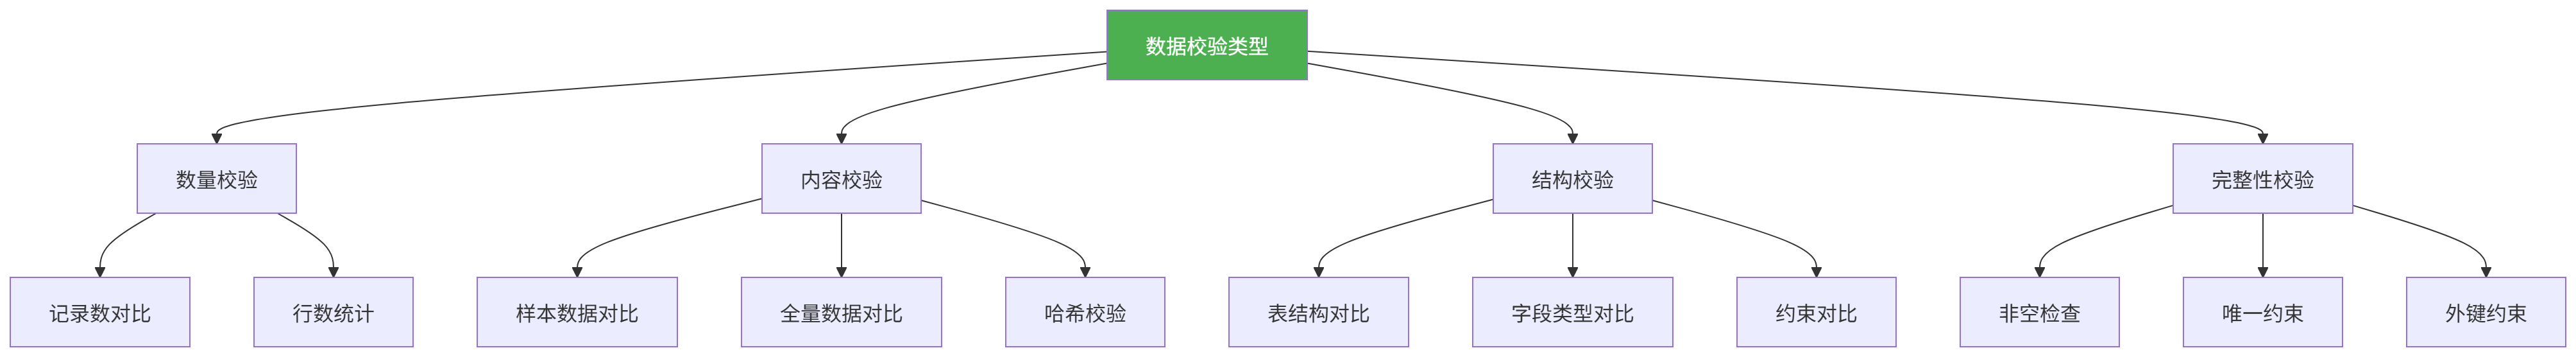
图表
4.2 数量校验
数量校验流程:
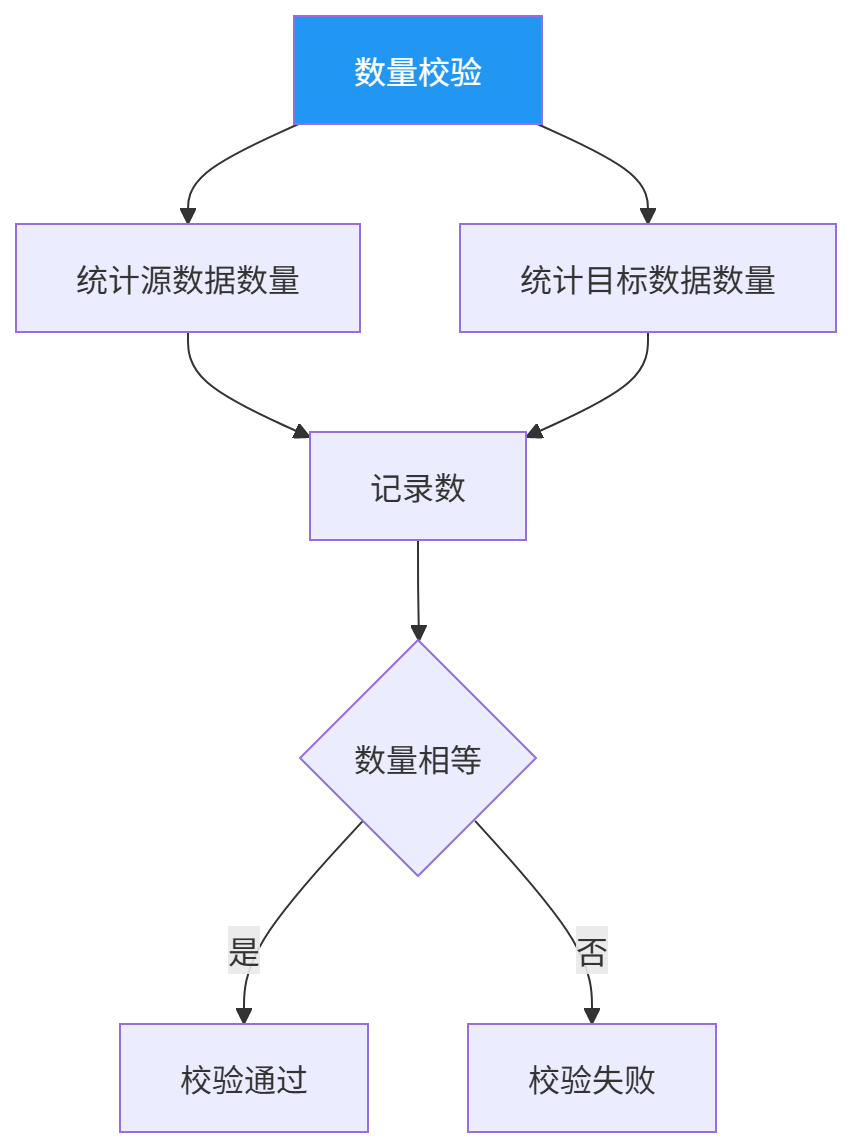
图表
数量校验代码示例:
class CountValidator:
    def __init__(self, source_db, target_db):
        self.source_db = source_db
        self.target_db = target_db

    def get_source_count(self, table_name):
        result = self.source_db.execute(f"SELECT COUNT(*) FROM {table_name}")
        return result.fetchone()[0]

    def get_target_count(self, table_name):
        result = self.target_db.execute(f"SELECT COUNT(*) FROM {table_name}")
        return result.fetchone()[0]

    def validate(self, table_name):
        source_count = self.get_source_count(table_name)
        target_count = self.get_target_count(table_name)

        is_valid = source_count == target_count

        return {
            'table': table_name,
            'source_count': source_count,
            'target_count': target_count,
            'is_valid': is_valid,
            'difference': source_count - target_count
        }
4.3 内容校验
内容校验流程:
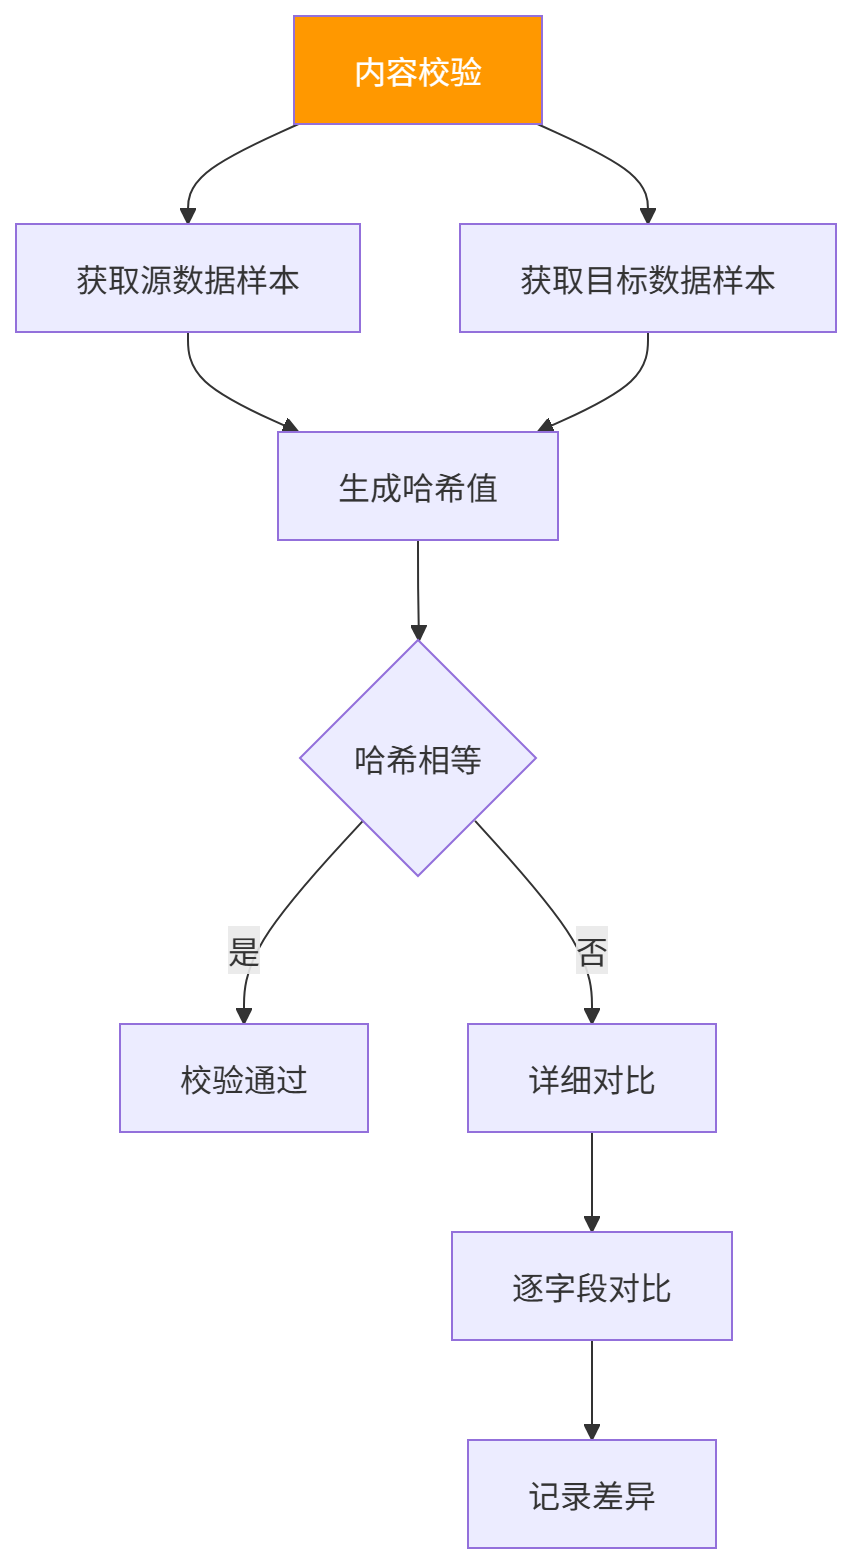
图表
内容校验代码示例:
import hashlib

class ContentValidator:
    def __init__(self, source_db, target_db):
        self.source_db = source_db
        self.target_db = target_db

    def generate_record_hash(self, record):
        sorted_keys = sorted(record.keys())
        hash_string = '|'.join(f"{k}={record[k]}" for k in sorted_keys)
        return hashlib.md5(hash_string.encode()).hexdigest()

    def get_sample_data(self, db, table_name, sample_size=100):
        result = db.execute(
            f"SELECT * FROM {table_name} ORDER BY id LIMIT %s",
            (sample_size,)
        )
        columns = [desc[0] for desc in result.description]
        return [dict(zip(columns, row)) for row in result.fetchall()]

    def validate_sample(self, table_name, sample_size=100):
        source_sample = self.get_sample_data(self.source_db, table_name, sample_size)
        target_sample = self.get_sample_data(self.target_db, table_name, sample_size)

        mismatches = []

        for source_record, target_record in zip(source_sample, target_sample):
            source_hash = self.generate_record_hash(source_record)
            target_hash = self.generate_record_hash(target_record)

            if source_hash != target_hash:
                mismatches.append({
                    'id': source_record.get('id'),
                    'source': source_record,
                    'target': target_record
                })

        return {
            'table': table_name,
            'sample_size': sample_size,
            'mismatches': mismatches,
            'is_valid': len(mismatches) == 0
        }

    def validate_full(self, table_name):
        source_count = self.source_db.execute(f"SELECT COUNT(*) FROM {table_name}").fetchone()[0]
        target_count = self.target_db.execute(f"SELECT COUNT(*) FROM {table_name}").fetchone()[0]

        if source_count != target_count:
            return {
                'table': table_name,
                'is_valid': False,
                'message': f"Count mismatch: source={source_count}, target={target_count}"
            }

        batch_size = 1000
        mismatches = []

        for offset in range(0, source_count, batch_size):
            source_batch = self.source_db.execute(
                f"SELECT * FROM {table_name} ORDER BY id LIMIT %s OFFSET %s",
                (batch_size, offset)
            ).fetchall()

            target_batch = self.target_db.execute(
                f"SELECT * FROM {table_name} ORDER BY id LIMIT %s OFFSET %s",
                (batch_size, offset)
            ).fetchall()

            source_columns = [desc[0] for desc in source_batch.description]
            target_columns = [desc[0] for desc in target_batch.description]

            for source_row, target_row in zip(source_batch.fetchall(), target_batch.fetchall()):
                source_record = dict(zip(source_columns, source_row))
                target_record = dict(zip(target_columns, target_row))

                source_hash = self.generate_record_hash(source_record)
                target_hash = self.generate_record_hash(target_record)

                if source_hash != target_hash:
                    mismatches.append({
                        'id': source_record.get('id'),
                        'source': source_record,
                        'target': target_record
                    })

        return {
            'table': table_name,
            'total_records': source_count,
            'mismatches': mismatches,
            'is_valid': len(mismatches) == 0
        }
4.4 结构校验
结构校验代码示例:
class StructureValidator:
    def __init__(self, source_db, target_db):
        self.source_db = source_db
        self.target_db = target_db

    def get_table_structure(self, db, table_name):
        result = db.execute(f"DESCRIBE {table_name}")
        columns = []
        for row in result.fetchall():
            columns.append({
                'name': row[0],
                'type': row[1],
                'null': row[2],
                'key': row[3],
                'default': row[4],
                'extra': row[5]
            })
        return columns

    def validate(self, table_name):
        source_structure = self.get_table_structure(self.source_db, table_name)
        target_structure = self.get_table_structure(self.target_db, table_name)

        source_columns = {col['name']: col for col in source_structure}
        target_columns = {col['name']: col for col in target_structure}

        missing_columns = [name for name in source_columns if name not in target_columns]
        extra_columns = [name for name in target_columns if name not in source_columns]
        type_mismatches = []

        for name in source_columns:
            if name in target_columns:
                source_type = source_columns[name]['type']
                target_type = target_columns[name]['type']
                if source_type != target_type:
                    type_mismatches.append({
                        'column': name,
                        'source_type': source_type,
                        'target_type': target_type
                    })

        return {
            'table': table_name,
            'missing_columns': missing_columns,
            'extra_columns': extra_columns,
            'type_mismatches': type_mismatches,
            'is_valid': not missing_columns and not extra_columns and not type_mismatches
        }
五、一致性验证流程
5.1 验证流程
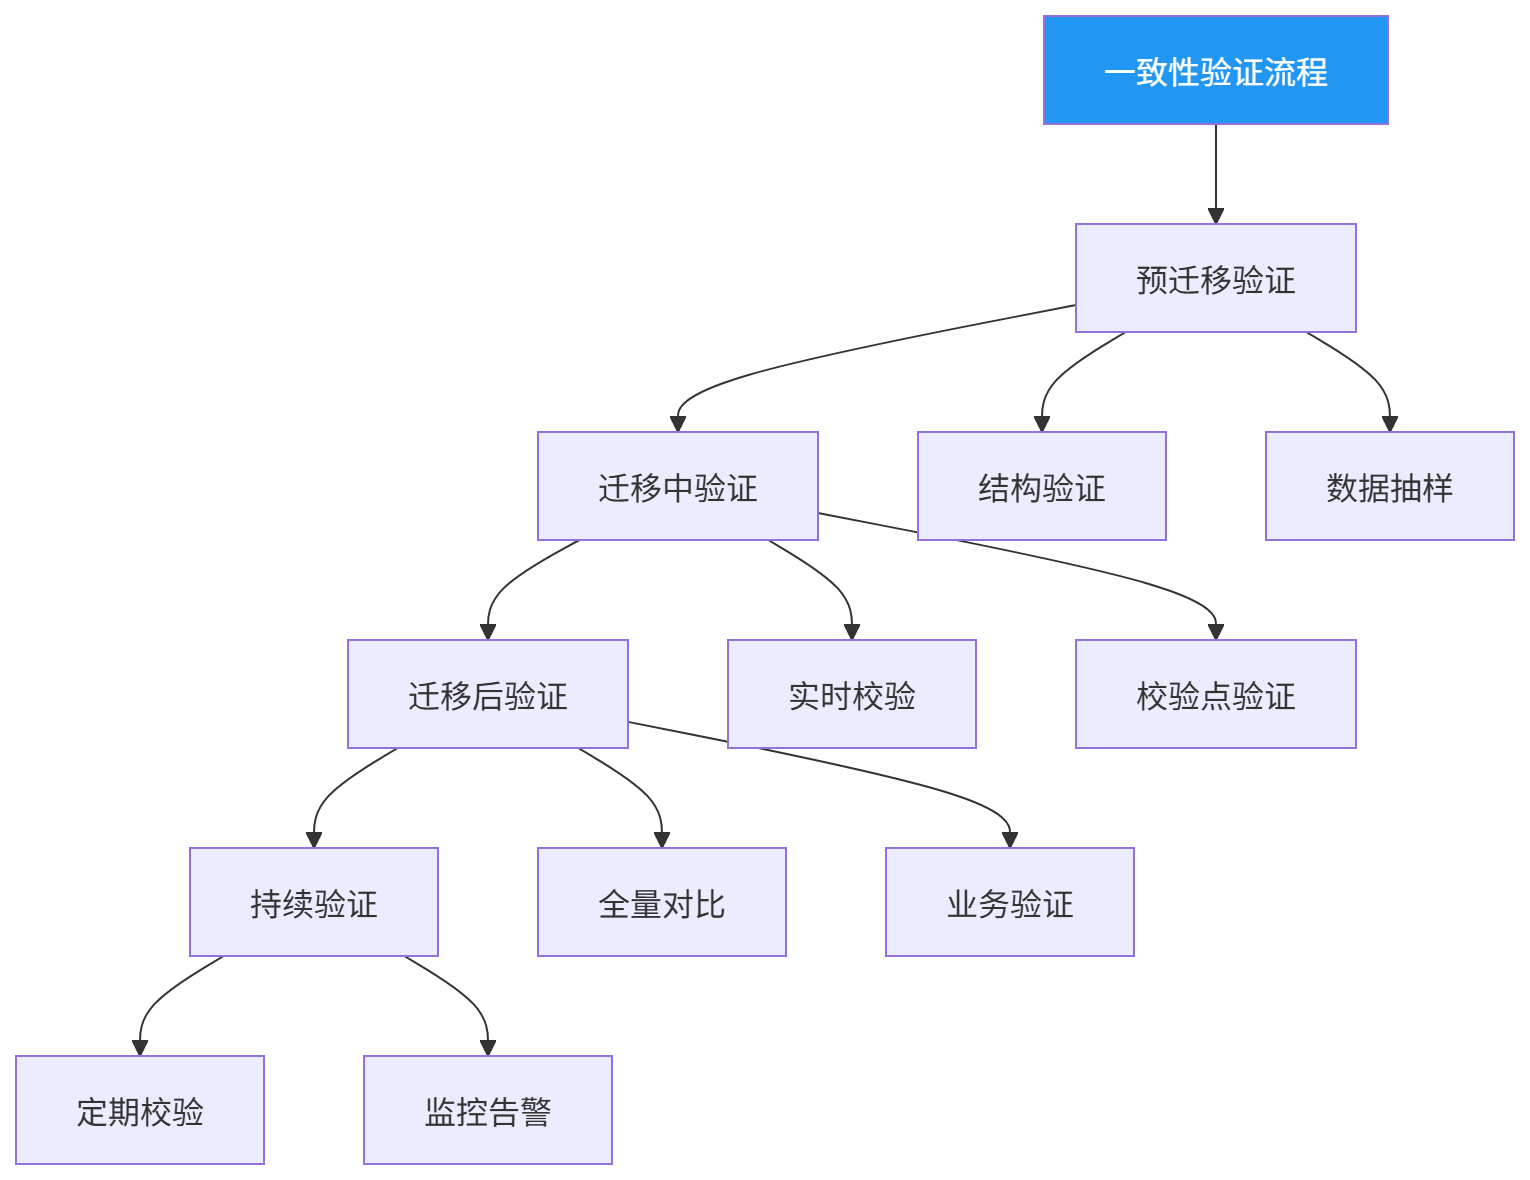
图表
5.2 验证报告
验证报告示例:
{
    "migration_id": "migration_001",
    "validation_time": "2024-01-15T10:00:00Z",
    "tables": [
        {
            "name": "users",
            "count_validation": {
                "source_count": 10000,
                "target_count": 10000,
                "is_valid": true
            },
            "content_validation": {
                "sample_size": 100,
                "mismatches": 0,
                "is_valid": true
            },
            "structure_validation": {
                "missing_columns": [],
                "extra_columns": [],
                "type_mismatches": [],
                "is_valid": true
            },
            "overall_status": "PASS"
        }
    ],
    "overall_status": "PASS",
    "total_tables": 1,
    "passed_tables": 1,
    "failed_tables": 0
}
六、常见问题
6.1 数据丢失
现象:目标数据少于源数据
解决方案:
方案 | 说明 |
|---|---|
事务保障 | 使用事务确保原子性 |
校验点 | 设置校验点支持断点续传 |
日志记录 | 记录每批数据处理日志 |
6.2 数据重复
现象:目标数据存在重复记录
解决方案:
方案 | 说明 |
|---|---|
唯一约束 | 设置唯一约束 |
幂等性设计 | 实现幂等写入 |
去重处理 | 迁移前去重 |
6.3 数据不一致
现象:源数据和目标数据不一致
解决方案:
方案 | 说明 |
|---|---|
实时同步 | 使用增量同步 |
全量对比 | 迁移后全量对比 |
数据修复 | 根据对比结果修复 |
6.4 完整性约束违反
现象:外键约束或唯一约束违反
解决方案:
方案 | 说明 |
|---|---|
顺序迁移 | 按依赖顺序迁移 |
延迟约束 | 迁移完成后启用约束 |
数据清理 | 清理不符合约束的数据 |
原创声明:本文系作者授权腾讯云开发者社区发表,未经许可,不得转载。
如有侵权,请联系 cloudcommunity@tencent.com 删除。
目录
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号